
While I was testing the new streaming channels for Neuron 4, I had an agent that reads files from a repository and answers questions about the code. In my terminal it worked perfectly. Then I moved it into a queue worker, connected Pusher to deliver the output to the browser, and the chat stopped in the middle of the answer. No exception in the agent, no error in the console. The agent had called a tool, the tool returned the content of a file, and that single event was bigger than the 10 KB Pusher accepts. It was simply refused, and the user interface waited forever for something that would never arrive.
This article is about how we solved that problem in Neuron AI, and why the solution ended up being a small streaming protocol with a companion TypeScript package for the frontend. If you are learning how to build Agentic applications, and you have never thought about what happens between your agent and the browser, this is a good moment to start, because it is where most full stack agentic applications break the first time they reach production.
What streaming an AI agent response means
Streaming an AI agent response means sending the output to the user piece by piece while the model is still generating it, instead of waiting for the complete answer. A language model can take several seconds, sometimes minutes, to finish a task. Showing the words as they are produced is what makes a chat interface feel alive rather than frozen.
With a simple chatbot the stream contains only text. An agent is different, because it does more than write. It reasons, it decides to call tools (a function that queries your database, reads a file, calls an external API), it receives the results of those tools, and only then it writes the final answer. All of these steps are part of the stream, and a good user interface shows them: “searching the orders table”, “reading config.yaml”, and so on.
In Neuron you get this stream by calling stream() on the agent instead of chat(). Each item you receive is a chunk object: a TextChunk for pieces of text, a ReasoningChunk for the reasoning of the model, a ToolCallChunk when the model asks to run a tool, and a ToolResultChunk with the output of that tool.
use App\Neuron\MyAgent;
use NeuronAI\Chat\Messages\UserMessage;

$stream = MyAgent::make()
    ->setThreadId('chat_id')
    ->stream(new UserMessage('How are you?'));

foreach ($stream as $chunk) {
    echo $chunk->content;
}
Keep the last two chunk types in mind. They are the ones that cause trouble later, because a tool call or a tool result can carry a lot of data: a JSON document, a list of records, the full content of a file.
Why AI agents end up running in background jobs
The easiest way to stream an agent is to keep the HTTP connection open in your controller and print every chunk to the browser as Server Sent Events. It works well for demos and for short answers. The problem is that agents are becoming more capable, and capable agents take time. An agent that calls five tools, waits for a slow API and then writes a long report can easily run past the PHP max_execution_time, the 60 seconds timeout of your Nginx proxy, or the limits of your load balancer.
So sooner or later you do what every PHP developer does with long tasks: you move the work into a queue. A Laravel job, a Symfony Messenger handler, a worker process. The agent now runs safely in the background, but a new question appears. Who is holding the stream? The worker produces chunks, but there is no browser attached to that process. Without something in the middle, all that output is thrown away.
Neuron 4 answers this with streaming channels. A channel is a component you attach to the agent that forwards every streamed event to an external transport: a Pusher compatible server, a Mercure hub, a Redis Pub/Sub channel, or anything else your application already uses. It no longer matters if stream() is called by a controller, a queue worker or a cron job. The events always reach the transport, and from there your frontend.
The run is also protected from the transport. If Pusher or Redis is down, the channel error is reported through the observability system and the agent keeps working. The chat history stays the source of truth, and the live stream is a layer of convenience on top of it. This detail will matter again when we talk about the frontend.
The hidden limits of real-time servers
Real-time servers were designed for notifications, chat messages and live counters: small payloads sent at a reasonable pace. Agent output does not fit this assumption, and you discover it in three different ways.
The first is message size. Pusher caps a single event at 10 KB, Laravel Reverb uses the same default, and Soketi allows 100 KB. A text chunk of a few words is fine, but a tool result containing a file or a list of database records is not. When the event is too large the server rejects it, and the UI never receives that piece of the conversation.
The second is frequency. Managed services often impose rate limits. A hosted Mercure instance, for example, allows from one to twenty publish requests per second depending on the subscription plan. A language model can produce dozens of text chunks per second, so sending one request per chunk quickly hits the limit.
The third is ordering. Not every server guarantees that messages arrive in the browser in the same order they were sent. For a notification it does not matter. For a stream of text it means words appearing in the wrong place, or a tool result arriving before the tool call that produced it.
None of these limits is a bug of the server. They are reasonable choices for the use cases those servers were built for. But if you want to use them for agents, someone has to adapt the stream to the transport. Until now that someone was you, writing custom code for every project.
How the Neuron Streaming Protocol works on the backend
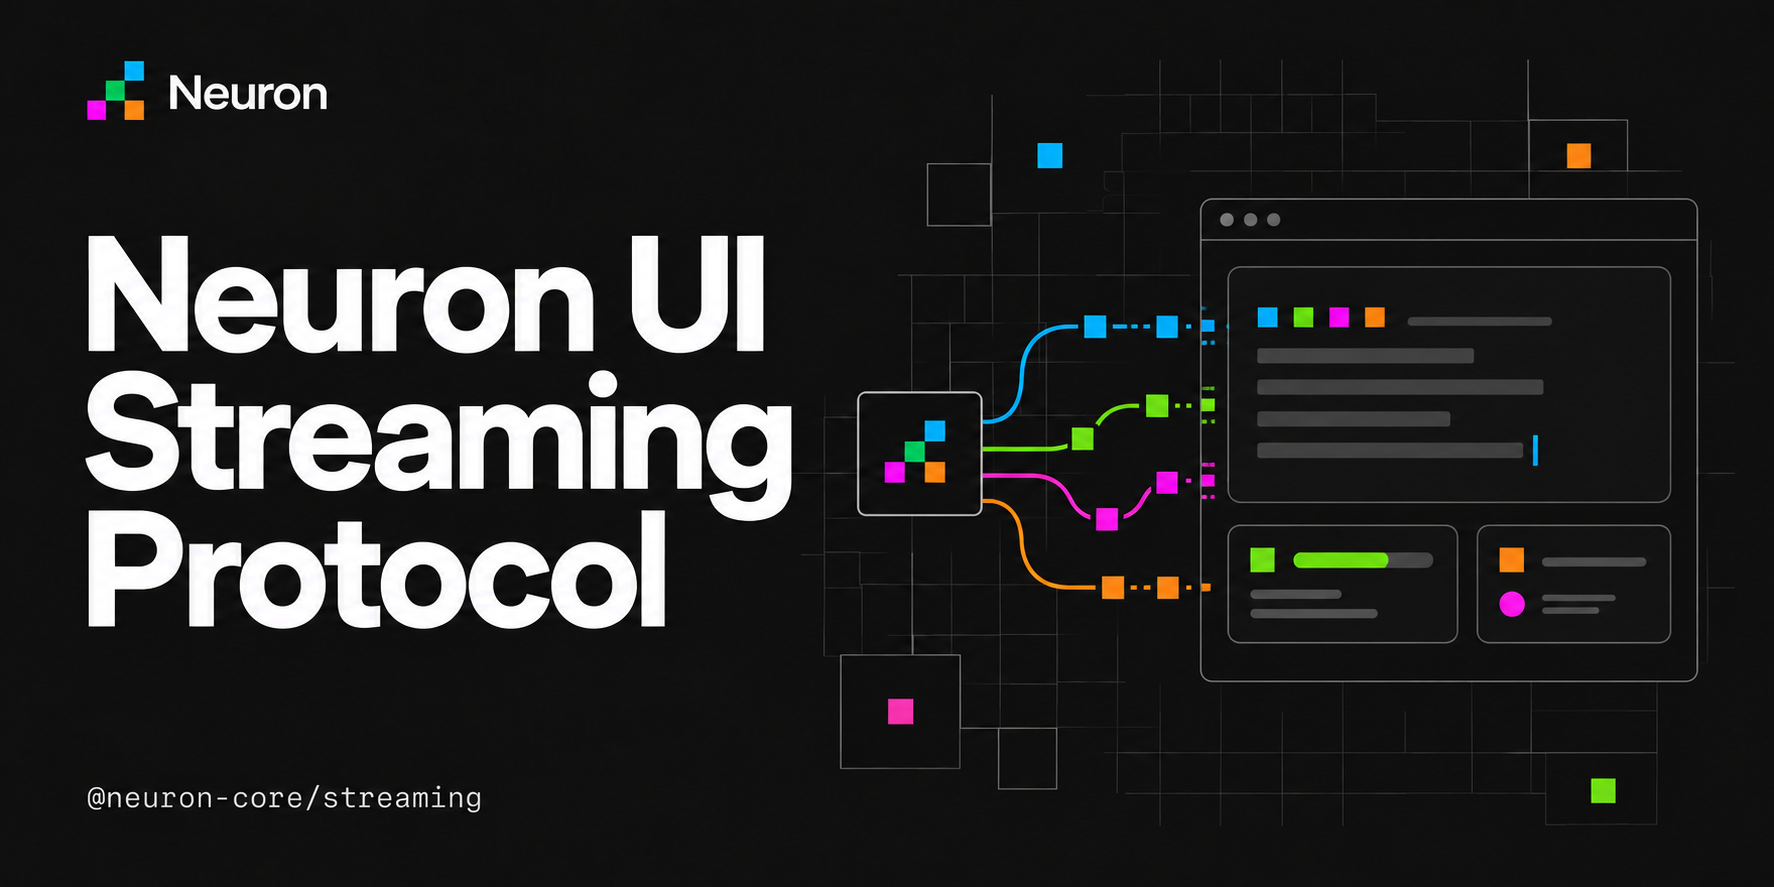
The Neuron Streaming Protocol is the format Neuron uses to deliver agent events through transports with size limits, rate limits or no ordering guarantees. Every event leaving the agent is wrapped in a small envelope with four fields: a streamId that identifies the execution, a sequence number, the event type, and its data. When an event is larger than the limit you configured, the channel splits it into consecutive fragments. Each fragment carries the original event type, its position, the total number of parts, and a slice of the payload. All the fragments share the sequence number of the original event, so the receiver knows they belong together.
You do not write any of this. You attach a channel to the agent and tell it the limits of your server. Here is an agent streaming through Pusher, or any Pusher compatible server like Reverb or Soketi:
use NeuronAI\Agent\Adapter\AgentChunkAdapter;
use NeuronAI\Workflow\Streaming\Channel\PusherChannel;
use NeuronAI\Workflow\Streaming\Channel\StreamingChannelInterface;
use Pusher\Pusher;

class MyAgent extends Agent
{
    // ...

    protected function streamAdapter(): ?StreamAdapterInterface
    {
        return new AgentChunkAdapter();
    }

    protected function channel(): StreamingChannelInterface
    {
        return new PusherChannel(
            client: new Pusher(...),
            channel: 'chat-'.$this->getThreadId(),
            maxRequestBytes: 10_000,
            batchSize: 10
        );
    }
}
The maxRequestBytes option is the size ceiling of your server. The default of 10 KB matches Pusher; if you run Soketi you can raise it. The batchSize option controls how many events are collected before being sent in a single request. Higher values mean fewer requests from your backend but a less fluid stream in the browser; lower values give a smoother experience at the cost of more requests. It is a trade-off you can tune once you see the real traffic of your application.
The stream adapter is required by channels. AgentChunkAdapter forwards the native Neuron chunks; later we will see how to replace it with an AG-UI or Vercel AI SDK adapter.
Mercure works the same way, with one more option for rate limits:
use NeuronAI\Agent\Adapter\AgentChunkAdapter;
use NeuronAI\Workflow\Streaming\Channel\MercureChannel;
use NeuronAI\Workflow\Streaming\Channel\StreamingChannelInterface;
use Symfony\Component\Mercure\Hub;

class MyAgent extends Agent
{
    // ...

    protected function streamAdapter(): ?StreamAdapterInterface
    {
        return new AgentChunkAdapter();
    }

    protected function channel(): StreamingChannelInterface
    {
        return new MercureChannel(
            hub: new Hub(...),
            topic: 'thread:'.$this->getThreadId(),
            maxRequestBytes: 1_048_576,
            maxRequestsPerSecond: 10,
            private: true
        );
    }
}
A self hosted Mercure hub has no rate limit, so maxRequestsPerSecond defaults to null. If you use a managed instance, set it to the limit of your plan. The channel then paces its requests to stay under that number, packing the events produced between two requests into a single update, and fragmenting anything above maxRequestBytes.
From this point the agent runs exactly as before. You dispatch it from a controller or a job, and the channel takes care of the delivery:
MyAgent::make()
    ->setThreadId($threadId)
    ->stream(new UserMessage($text));
Reassembling the stream in the browser with @neuron-core/streaming
Splitting events on the server is only half of the job. The browser now receives envelopes that can be fragmented, out of order, or duplicated after a reconnection, and it has to turn them back into a clean sequence of events before your components can render anything. Doing this by hand is the kind of code that works on your machine and fails in front of a customer.
This is why Neuron 4 ships with a first party TypeScript package, @neuron-core/streaming. It orders the envelopes of each execution, joins the fragments, ignores duplicates, and tells you when something is missing. It has no dependencies and works in modern browsers and in Node.js 22 or later.
npm install @neuron-core/streamingWith Pusher, you pass the channel from your existing pusher-js client. The important detail is the order of operations: subscribe first, wait for the subscription to succeed, and only then start the agent, otherwise the first events can be lost.
import Pusher from 'pusher-js';
import { subscribeToPusher } from '@neuron-core/streaming';

const pusher = new Pusher('YOUR_APP_KEY', { cluster: 'eu' });
const channel = pusher.subscribe(`chat-${threadId}`);

channel.bind('pusher:subscription_succeeded', () => {
  const subscription = subscribeToPusher(channel, {
    onEvent: ({ streamId, type, data }) => renderEvent(streamId, type, data),
    onGap: reason => reloadConversation(reason),
  });

  // Now it is safe to ask the backend to start the agent
  startAgent(threadId, message);
});
With Mercure you pass an EventSource opened on the hub. The browser handles the connection and the automatic reconnection; the package unpacks the updates and delivers one reconstructed event at a time.
import { subscribeToMercure } from '@neuron-core/streaming';

const url = new URL('https://hub.example.com/.well-known/mercure');
url.searchParams.append('topic', `thread:${threadId}`);
const source = new EventSource(url, { withCredentials: true });

const subscription = subscribeToMercure(source, {
  onEvent: ({ streamId, type, data }) => renderEvent(streamId, type, data),
  onGap: reason => reloadConversation(reason),
});
The onEvent callback always receives complete events, in the order they were produced. You never see a fragment. The onGap callback is called when an event is definitely missing, for example after a disconnection the server could not replay. At that point the right move is the one I mentioned before: reload the conversation from the chat history, which is always complete, and create a fresh subscription. The end of every execution is signaled by one of three terminal events, completed, interrupted or failed, so the user is never left with a spinner that never stops.
If you use plain WebSockets or a Redis bridge, the same core is available through createChannelConsumer(). You decode the message, call accept() with the envelope, and get the same ordered events back.
Using it with React, Vue, AG-UI and the Vercel AI SDK
The package does not know which UI framework you use, and it does not need to. The callback API fits naturally into the lifecycle of a component: subscribe when it mounts, close the subscription when it is destroyed. In React this is a useEffect that returns subscription.close(); in Vue you assign the events to a ref and call close() in onUnmounted.
useEffect(() => {
  const subscription = subscribeToPusher(channel, {
    onEvent: event => setEvents(previous => [...previous, event]),
    onGap: reason => reloadConversation(reason),
  });

  return () => subscription.close();
}, [channel]);
The more interesting case is when you want to use an agent UI library instead of building the interface yourself. On the backend you replace AgentChunkAdapter with one of the protocol adapters Neuron already provides, AGUIAdapter for AG-UI clients like CopilotKit, or VercelAIAdapter for the Vercel AI SDK. The channel transports those protocol events with the same envelopes and fragmentation. On the frontend, createProtocolStream() turns the subscription into a standard ReadableStream of protocol objects, ready to be handed to the library.
import { createProtocolStream, subscribeToPusher } from '@neuron-core/streaming';

const stream = createProtocolStream(
  callbacks => subscribeToPusher(channel, callbacks),
  event => event
);
This is the part I care about the most. Until now, a frontend developer who wanted to build an agentic interface with CopilotKit or the Vercel AI SDK on top of a PHP backend had to accept a long lived HTTP connection, or write the transport layer from scratch. Now the backend team can run the agent in a queue, use the real-time server the company already pays for, and the frontend team can keep working with the libraries they know. The two sides meet on a documented protocol instead of a custom solution that only one person in the team understands.
Letting your coding agent do the integration
There are a few details in this integration that are easy to miss: subscribing before starting the run, waiting for the connection to be ready, choosing the right adapter on both sides, reloading from history after a gap. They are the kind of details a coding agent gets wrong if it relies only on what it learned during training, because this protocol did not exist when those models were trained.
For this reason Neuron provides skills, a set of precise instructions you can give to Claude Code, Cursor or any coding agent that supports them. Use /neuron-streaming for a generic integration, or the framework specific skills /neuron-laravel-integration and /neuron-symfony-integration if your application is built on one of those frameworks. A prompt as simple as this is usually enough:
/neuron-laravel-integration Move the SupportAgent into a queued job and stream its output to the chat component through Reverb, using @neuron-core/streaming on the frontend.The skill gives the agent the exact sequence to follow on both sides, so you can spend your attention reviewing the architecture rather than debugging a missing event.
Where this leaves full stack agentic applications in PHP
When I started working on channels I thought the hard part would be moving the agent out of the HTTP request. It turned out to be the last mile: the real-time server, its limits, and the browser on the other side. Most agentic frameworks, in PHP, Python or TypeScript, stop at the server and leave that mile to you. With Neuron 4 the agent, the transport and the frontend speak the same protocol, so you can pick Pusher, Reverb, Soketi, Mercure or Redis based on what your infrastructure already has, and pick React, Vue, CopilotKit or the Vercel AI SDK based on what your frontend team prefers.
If you want to try it, the streaming documentation covers every channel in detail, and the @neuron-core/streaming README explains the frontend API. If you build something with it, or if you find a real-time server we do not support yet, let me know. That is exactly the kind of feedback that shaped this release.